

Maximum of 25 job preferences reached.
Top Remote Site Reliability Engineer Jobs in Los Angeles, CA
Software • Defense
Own reliability, scalability, security, observability, and incident response for production applications across AWS and on-premises DoD environments. Build monitoring and alerting, define SLIs and SLOs, lead post-incident reviews, automate infrastructure with Terraform and Ansible, operate Kubernetes clusters, embed RMF and STIG controls, reduce operational toil, and support secure air-gapped deployments.
Top Skills:
AlloyAnsibleAWSAws GovcloudBashDatadogElk StackGithub ActionsGitlab Ci/CdGitopsGoGrafanaHyper-VIstioJenkinsKubernetesLinkerdLokiNutanixPrometheusProxmoxPythonRmfSecurity+StigsTerraformVMware

Information Technology • Security • Cybersecurity
Own production operations and highly available cloud infrastructure for regulated government environments. Lead incident response, root-cause analysis, disaster recovery testing, compliance operationalization, audit readiness, vulnerability management, and continuous monitoring. Build automation, secure CI/CD pipelines, infrastructure-as-code, observability, and compliance tooling across Kubernetes, Linux, containers, and cloud platforms. Partner with security, compliance, and engineering teams to improve reliability, deployment safety, and regulatory sustainment.
Top Skills:
Aws GovcloudBashCi/CdDod Il4Dod Il5FedrampGitopsGoGrafanaKubernetesLinuxNist 800-53PrometheusPythonStigTerraformUnixZero Trust

Reposted 2 Months AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
As a Senior Site Reliability Engineer, you'll design and build complex systems, support Atlas platform operations, automate processes, and ensure high availability of services.
Top Skills:
AWSAzureDnsGCPGoHTTPLinuxPythonRubyTls

Cloud • Software • Analytics
Develop and operate Arista’s FedRAMP CloudVision SaaS platform at scale. Responsibilities include improving reliability, scalability, observability, autoscaling, disaster recovery, capacity planning, CI/CD, network architecture, cost optimization, and cloud application security. The role develops and manages Kubernetes-native services, distributed databases, and automation using technologies such as GCP, GKE, Go, Python, Ansible, Pulumi, and Bash. Participation in a FedRAMP on-call rotation is required.
Top Skills:
AnsibleBashCi/CdDistributed DatabasesFedrampGoGoogle Cloud Platform (Gcp)Google Kubernetes Engine (Gke)KubernetesPulumiPythonSaaS
Fitness • Healthtech • Software
Own reliability and security of CI/CD and production services: define SLI/SLOs, lead incident response and postmortems, build observability (Datadog), operate Kubernetes and IaC (Terraform), harden pipelines with SAST/DAST/SCA and policy-as-code, and coach teams on reliability and operational best practices.
Top Skills:
AWSCi/CdConftestDastDatadogDockerGithub ActionsGoInfrastructure As CodeKubernetesKyvernoOpa/RegoPythonSastScaTerraformTypescript
Legal Tech • Software
Design and improve observability (monitoring, logging, tracing, SLIs/SLOs), build automation and CI/CD, lead incident response and reliability improvements, mentor SREs, run on-call, and apply AI/ML to operational signals to forecast and reduce risks.
Top Skills:
AWSBashCi/CdDistributed TracingGoInfrastructure As CodeKubernetesLoggingMonitoringPythonSlisSlos
Fintech • Real Estate • Software
Lead reliability and observability efforts across the org: design and maintain Kubernetes and AWS infrastructure, build CI/CD pipelines, drive IaC standards (Terraform/Crossplane), partner with 16+ teams to roll out tools and processes, participate in on-call rotation and incident response, and use AI tools to accelerate work.
Top Skills:
Ai ToolsArgoAurora PostgresAWSCi/Cd PipelinesCrossplaneDatadogDocumentdb (Mongo)EcsEksGithub ActionsHelmKubernetesMongoDBPostgresRdsTerraform
Cloud • Security • Software • Cybersecurity
Architect, build, and support reliable network infrastructure and automation for Akamai’s distributed cloud platform. Develop Bash and Python tooling, establish deployment standards, define SLOs, mentor engineers, and troubleshoot complex network issues. The role requires expertise in large-scale distributed systems, TCP/IP, BGP, Linux networking, configuration management, CI/CD, and open-source networking software, with participation in on-call rotations.
Top Skills:
AnsibleArgocdBashBgpBirdChefFirewallsFrrGithub ActionsGoGobgpJenkinsLinux NetworkingLoad BalancingPuppetPythonRustSaltstackSlack BotsTcp/Ip
15 Days AgoSaved
Cloud • Security • Software • Cybersecurity
Develop and operate Akamai’s Linux-based cloud infrastructure, including bare-metal and virtual machine platforms, kernels, operating systems, and KVM/QEMU virtualization. Build software, automation, observability, and infrastructure enhancements at scale; troubleshoot complex distributed-system issues; collaborate across engineering and operations; mentor team members; and participate in on-call service restoration.
Top Skills:
AnsibleChefKubernetesKvm/QemuLinuxLinux KernelNested VirtualizationPuppetSaltstack

Healthtech • Pharmaceutical • Manufacturing
Support operational deployments and maintenance for Core Speech production systems. Implement and maintain monitoring, alerting, performance reporting, and capacity planning. Participate in on-call rotation for off-hours reliability support. Drive improvements to system performance and architecture, and collaborate on projects while complying with corporate and quality standards.
Other
Lead platform infrastructure reliability initiatives for a microservices-based cloud SaaS solution. Design scalable, automated, observable infrastructure; define platform roadmaps; guide engineering teams through design reviews; reduce operational toil; build monitoring and alerting; and participate in on-call incident response. The role uses AWS, Kubernetes on EKS, Istio, infrastructure-as-code, GitLab, Argo CD, and Datadog.
Top Skills:
Amazon EksArgo CdAWSAws CdkDatadogEc2GitlabIstioKubernetesRdsS3Terraform
Information Technology • Security • Software • Cybersecurity
Lead reliability strategy across eight engineering groups by defining SLIs, SLOs, and error budgets; strengthening incident response, alerting, postmortems, change safety, and failure testing; and coaching teams to own reliability. The role remains hands-on through production investigations, tooling, dashboards, and reference implementations. It also leads AI adoption in incident management and observability while partnering with architecture, platform, and product teams to improve distributed-system resilience.
Top Skills:
Ai ToolsAWSDatadogDynamoDBElasticsearchGoInfrastructure As CodeKafkaKubernetesObservability ToolingRedisTypescript
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free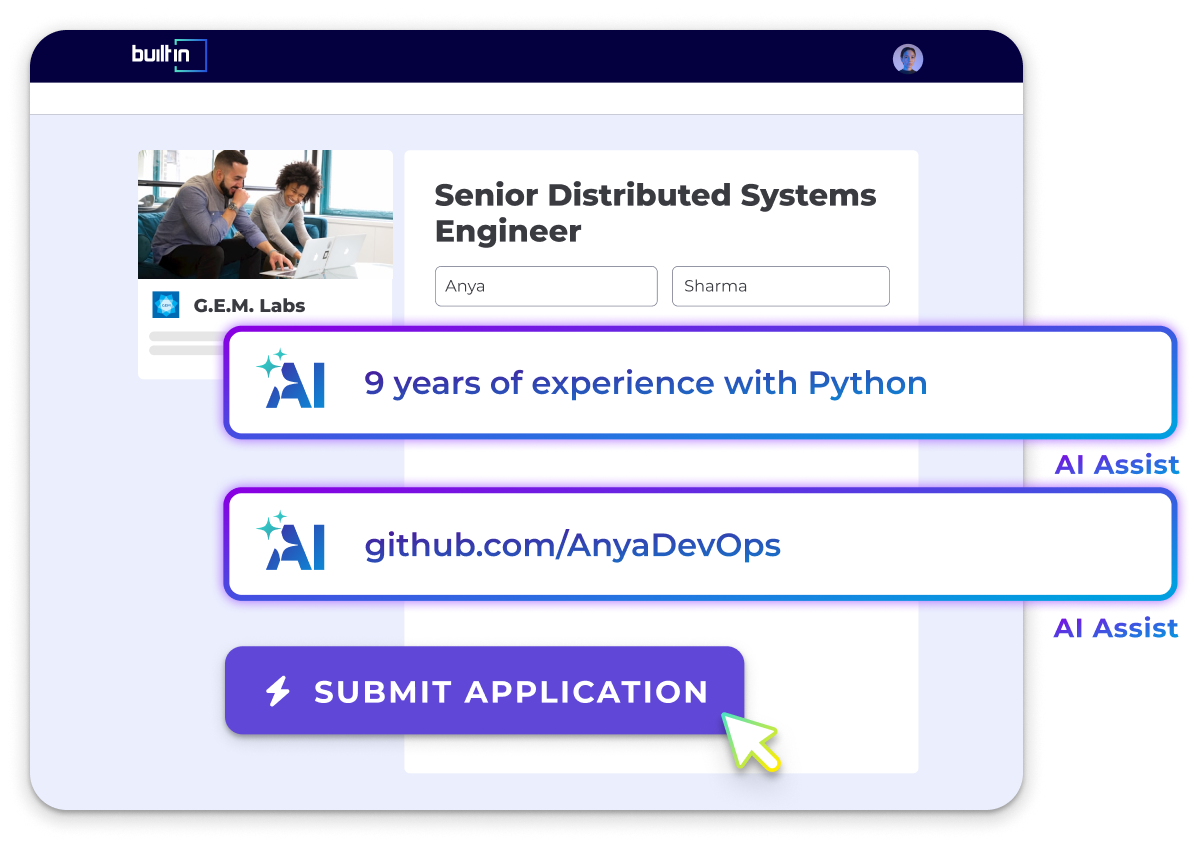
Insurance
Designs and operates reliable hybrid application platforms, leading CI/CD, infrastructure automation, cloud resource management, monitoring, security scanning, container orchestration, and database self-service tooling. The role owns the enterprise CI/CD technology stack and hosting strategy across on-premises, hybrid, and cloud environments. It requires extensive collaboration with engineering, infrastructure, security, application, QA, and governance teams, along with 24/7 mission-critical support and technical leadership.
Top Skills:
AnsibleApache CamelAWSCi/CdCloudFormationConfluenceDatabase SystemsDockerGitGithub ActionsGitlab CiGradleHelmInfrastructure As CodeJenkinsJIRAKubernetesLinuxMavenMonitoring And AlertingNetworkingPythonSonatypeTerraformVulnerability Scanning
Reposted 2 Months AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
The Senior Site Reliability Engineer will develop and support distributed storage services, ensuring reliability and operational safety, with a focus on automation and efficiency.
Top Skills:
AWSAzureDnsGoGoogle Cloud PlatformKubernetesLinuxPythonTcp/IpTls

Cloud • Information Technology • Security • Virtual Reality • Cybersecurity
Support reliability, security, scalability, and performance of the TAK CI/CD pipeline and critical infrastructure. Monitor system health, respond to incidents, patch systems, optimize performance and costs, improve DevOps practices, automate operations, and maintain technical documentation. Requires systems and network administration experience, Linux and cloud expertise, containerization, CI/CD knowledge, Zero Trust implementation experience, Security+ certification, and an active T3 investigation.
Top Skills:
AWSCi/Cd PipelinesContainerizationLinuxZero Trust

Automotive
Design and implement scalable cloud infrastructure, monitor performance, automate processes, ensure security and compliance, and lead a DevOps team.
Top Skills:
AWSBashCi/CdDockerElk StackGCPGrafanaKubernetesPrometheusPythonTerraform

Artificial Intelligence • HR Tech • Professional Services • Software
Evaluate AI-generated documents, spreadsheets, and presentations for accuracy, rigor, domain quality, and presentation quality in incident management, reliability, and SRE. Apply specialized rubrics, identify factual and aesthetic errors, and provide structured written feedback. This is a fully remote, flexible independent-contractor engagement requiring at least five years of relevant professional experience, English fluency, and proficiency with Microsoft Office and Google Workspace.
Top Skills:
Google SlidesGoogle WorkspaceMS OfficePowerPoint

Artificial Intelligence • Big Data • Healthtech • HR Tech • Machine Learning • Software • Big Data Analytics
Own the reliability, performance, resilience, observability, and security of AWS and Kubernetes infrastructure supporting products and AI/ML workloads. Define SLOs, lead incident response and root-cause analysis, build Terraform automation, optimize cloud costs, reduce operational toil, and establish deployment standards that help engineers ship reliably. Participate in on-call rotations and maintain HIPAA-compliant infrastructure.
Top Skills:
AWSClaudeDatadogGitlabGoHipaaIstioKubernetesNatsPostgresPythonSoc 2TerraformTypescript

Artificial Intelligence • Software
Architects and owns highly available infrastructure and Kubernetes-based platforms supporting autonomous systems. Builds Golang backend services, platform tooling, observability systems, dashboards, alerts, and log aggregation. Partners with product teams to launch services, performs performance analysis, manages cloud upgrades, and participates in incident response and postmortems. Collaborates on cloud security risk assessments, intrusion detection, threat-feed systems, risk mitigation, and SaaS payment processes. Provides architectural leadership and mentorship across engineering teams.
Top Skills:
ArgocdArgocd Image UpdaterArtifactoryAWSGithub ActionsGoJavaScriptKubernetesPythonRustTerraform
Big Data • Analytics
Own production reliability across Azure, colocation, and edge Kubernetes environments. Build observability, alerting, automated recovery, high-availability architectures, deployment automation, and cost optimization. Lead incident response, troubleshoot distributed systems, improve disaster recovery and operational maturity, support platform lifecycle management, and mentor engineers. Participate in separate weekday and weekend on-call rotations for customer-facing systems.
Top Skills:
AksAnsibleConfluenceDatadogEksGithub ActionsGrafanaHelmIstioJIRAKubernetesLokiLonghornAzureMicrosoft EntraMicrosoft TeamsNatsOctopus DeployOpentelemetryPostgisPostgresPrometheusRabbitMQRancherRke2Terraform

Information Technology • Cybersecurity
Designs, operates, and improves scalable cloud and on-premise infrastructure, CI/CD pipelines, Kubernetes platforms, data streaming systems, and observability tooling. Owns AWS reliability, security, cost efficiency, automation, progressive deployments, incident response, and production troubleshooting. Partners with software engineering teams to integrate services and drive continuous improvements in system performance, scalability, and uptime.
Top Skills:
AlertmanagerAmazon RdsApache KafkaArgocdAWSChaossearchConfluent CloudElasticsearchGithub ActionsGoGoogle Cloud PlatformGrafanaGrafana CloudHelmIstioJenkinsKubernetesKustomizeLaunchdarklyAzureNode.jsOpensearchOpsgeniePagerdutyPosthogPrometheusPythonRedisTerraformTerragrunt
Aerospace • Hardware • Software • Defense • Manufacturing
Build scalable automated solutions for device fleet management, own and optimize MDM platforms, write OS-level scripts for self-healing, gather telemetry to prevent end-user disruption, translate compliance (CMMC) into code-managed baselines, and create dashboards and alerts measuring end-user SLOs.
Top Skills:
AnsibleBashChefFleet DmIntuneJAMFOsqueryPowershellPulumiPuppetPythonSaltTerraformWorkspace One

Cloud • Information Technology • Cybersecurity • Infrastructure as a Service (IaaS)
Owns reliability, observability, and incident response for a GPUaaS platform. Defines SLOs, builds monitoring and alerting systems, leads major incidents and post-incident reviews, automates operational processes, maintains runbooks, manages on-call operations, coordinates with engineering teams, drives chaos testing, reports SLA performance, and mentors junior engineers.
Top Skills:
DatadogGoGpuaasGrafanaGremlinHpcKubernetesLitmusOpentelemetryPrometheusPython
Artificial Intelligence • Cloud • Software • Infrastructure as a Service (IaaS)
Ensure stability and resilience of Runpod's distributed AI platform by defining SLIs/SLOs, leading incident response, building observability and reliability tooling, automating operational workflows, and partnering with engineering teams to reduce toil and improve production readiness.
Top Skills:
BashCi/CdContainerized Production SystemsGoGpu Observability ToolingGrafanaInfrastructure As CodeLinuxPrometheusPython
Cloud • Security • Software • Cybersecurity
Design, build, and operate scalable infrastructure and CI/CD/IaC systems. Implement observability (monitoring, logging, alerting), automate reliability improvements, mentor engineers, collaborate on incident response, and participate in on-call rotations to maintain Akamai Cloud services.
Top Skills:
AlertingAnsibleBashChefCi/CdGithub ActionsGitlab Ci/CdGoInfrastructure As CodeJenkinsLoggingMonitoringPuppetPythonSaltstackTelemetryTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Los Angeles, CA Companies Hiring Remote Site Reliability Engineers
See All






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
