

Maximum of 25 job preferences reached.
Top Remote Site Reliability Engineer Jobs in Los Angeles, CA
Aerospace • Hardware • Robotics • Software
Own and evolve a portable data platform infrastructure across commercial cloud, government cloud, and on-premises environments. Responsibilities include infrastructure as code, security and compliance, observability, SLOs, incident response, capacity planning, backups, upgrades, deployment tooling, and runbooks. The role will establish SRE practices, support regulated customer deployments, collaborate with distributed systems engineers, and mentor a future SRE hire.
Top Skills:
Aws GovcloudCi/CdKubernetesTerraform
4 Days AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Lead architecture and delivery for GitLab Hosted Runners, writing and operating production Go software across runner control planes, autoscaling, cloud integrations, and job execution. Improve reliability, workload isolation, observability, capacity planning, and cost attribution. Participate in on-call, investigate production failures, automate operations, mentor engineers, and coordinate technical initiatives across teams supporting GitLab.com and GitLab Dedicated.
Top Skills:
AutoscalingCi/CdGitlab RunnerGoInfrastructure AutomationKubernetesLinuxNetworkingObservabilityPublic Cloud

Artificial Intelligence • Big Data • Healthtech • HR Tech • Machine Learning • Software • Big Data Analytics
Sets company-wide technical direction for a cloud platform spanning reliability, security, architecture, and developer experience. Owns platform strategy, standards, KPIs, SDLC mechanisms, risk resolution, and cross-functional initiatives. Partners with engineering leadership on roadmaps, secures production systems for regulatory compliance, mentors senior engineers, and raises hiring standards. The role requires deep expertise in cloud infrastructure, Terraform, Kubernetes, Go, Python, and regulated environments such as healthcare.
Top Skills:
AWSGitlabGoGrafanaIstioKubernetesNatsOpensearchPostgresPythonTerraform

7 Days AgoSaved
Easy Apply
Easy Apply
Artificial Intelligence • Cloud • Computer Vision • Hardware • Internet of Things • Software
Lead Samsara’s AI initiatives across the software development lifecycle, including developer agents and SRE AI. Set strategy, select experiments, make build-versus-buy decisions, control infrastructure and token costs, scale automated incident response, and build trust in AI-driven actions. Manage and grow a team of five to ten senior engineers while partnering directly with R&D leaders and developers.
Top Skills:
Ai AgentsClaudeCloud InfrastructureCodexIncident Response AutomationIotModel Context Protocol (Mcp)Sre Tooling

Computer Vision • Software
Monitor and improve the reliability, observability, and performance of AWS and Kubernetes platforms. Build dashboards and alerts, respond to incidents, conduct root cause analysis, maintain operational documentation, improve deployment reliability, reduce MTTR, and support CI/CD pipelines and infrastructure automation. The role is fully remote and supports federal healthcare systems.
Top Skills:
AgileAWSBashCi/CdGrafanaInfrastructure As CodeKubernetesLokiPrometheusPythonTerraform

Artificial Intelligence • Information Technology • Software • Defense
Lead the technical direction for VOR’s infrastructure, deployment automation, observability, security, and reliability practices. Build AWS and Kubernetes environments, improve CI/CD pipelines, establish monitoring and service-level objectives, lead incident response, validate backup and disaster recovery procedures, and strengthen identity, access, and software supply chain controls. Partner with application engineers, mentor technical teams, document decisions, and improve operational readiness, performance, capacity, and cost across platform services and AI-enabled workflows.
Top Skills:
AWSAws GovcloudDnsEksGitlab Ci/CdGoHelmKeycloakKubernetesLinuxLoad BalancingOauthOidcPrivate Container RegistriesPythonRoutingShell ScriptingTerraformTlsWorkload Identity
Healthtech • Social Impact • Transportation • Telehealth
Supports production application and infrastructure reliability by diagnosing complex issues, restoring services, managing escalations, and conducting root cause analysis. Develops monitoring, alerting, automation, documentation, and outage-prevention solutions across Java applications and AWS platforms. Collaborates with service teams and customers during incidents, troubleshoots cloud and software issues, improves platform performance, and may lead projects.
Top Skills:
ActivemqAi-Assisted Coding ToolsAlertingAPIsAWSAws CognitoCloudwatchCurlDatadogDynatraceFirebaseGitlabGoogle AnalyticsIp ProtocolsJavaMonitoringNosql DatabasesPostmanRelational DatabasesRestful Web ServicesSQL

Aerospace
Designs and maintains scalable, reliable infrastructure and automation. Responsibilities include monitoring systems, managing incident response, developing deployment tools, analyzing capacity, improving CI/CD and infrastructure provisioning, enforcing security practices, participating in on-call rotations, and leading reliability initiatives across engineering teams.
Top Skills:
AtlantisAuroraAWSAws CodebuildAzureCircleCIDatadogDockerEcsGithub ActionsGoGrafanaKubernetesPostgresPythonRdsTerraformTerragrunt
Cloud • Security • Software • Cybersecurity
Architect, build, and support reliable network infrastructure and automation for Akamai’s global cloud platform. Mentor engineers, establish deployment and code-quality standards, define SLOs, develop tools using Python and Bash, collaborate with network developers, and troubleshoot complex distributed-system and networking issues. Participate in on-call rotations while improving platform scalability, availability, and performance.
Top Skills:
AnsibleArgocdBashBgpBirdChefFirewallsFrrGithub ActionsGoGobgpJenkinsLinux NetworkingLoad BalancingPuppetPythonRustSaltstackSlack BotsTcp/Ip

Artificial Intelligence • HR Tech • Professional Services • Software
DevOps, SRE, and infrastructure experts design technical tasks, solutions, benchmarks, and evaluation rubrics for generative AI models. They assess AI-generated infrastructure configurations, Kubernetes deployments, Terraform modules, CI/CD pipelines, cloud architectures, reliability, security, scalability, and cost optimization. The role also requires providing detailed expert feedback and developing realistic troubleshooting, incident management, and disaster recovery scenarios based on production engineering practices.
Top Skills:
ArgocdAWSAws CloudformationBashDockerGithub ActionsGoGoogle Cloud PlatformGrafanaJenkinsKubernetesAzureOpentelemetryPrometheusPulumiPythonTerraform
Artificial Intelligence • Information Technology • Software • Defense
Leads the design and operation of secure, reliable cloud infrastructure for federal digital services. Responsibilities include Infrastructure as Code, Kubernetes platforms, CI/CD automation, observability, monitoring, reliability engineering, disaster recovery, vulnerability remediation, production-readiness reviews, and operational runbooks. The role coordinates with application, security, API, data, and managed-cloud teams while resolving complex infrastructure issues and establishing service-level objectives and resilience practices.
Top Skills:
Amazon EksAWSCi/CdDatadogFluxHelmKubernetesLinuxTerraformTerragrunt
Artificial Intelligence • Information Technology • Software • Defense
Provide production reliability engineering for GSA digital services by defining SLOs, building observability and operational dashboards, automating remediation, maintaining runbooks, supporting on-call incident response, conducting root-cause analysis, improving application and infrastructure performance, and supporting production readiness, capacity planning, resilience, and disaster recovery.
Top Skills:
AlertingAmazon EksAutomationAWSCi/CdDatadogDisaster RecoveryDistributed TracingDockerFluxHelmIncident ManagementKubernetesLoggingMonitoringObservabilitySlosTerraform
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free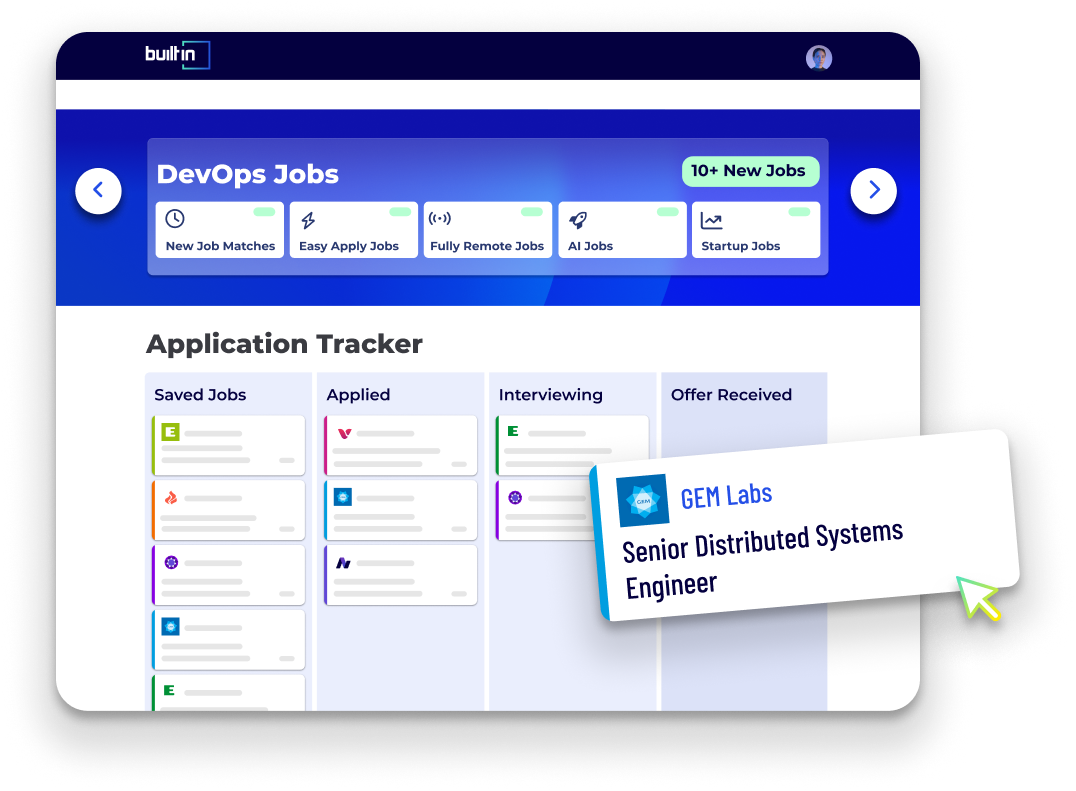
Cloud • Security • Software • Cybersecurity
Lead reliability engineering for Akamai’s serverless AI inference platform. Responsibilities include observability strategy, SLO/SLI frameworks, production automation, incident management, deployment safety, canary releases, rollback automation, architecture reviews, and mentoring SREs. The role partners across teams to improve operational readiness and reliability for distributed systems, Kubernetes environments, and GPU-based workloads.
Top Skills:
Ci/CdContainerizationGoGpu InfrastructureInfrastructure-As-CodeKubernetesObservabilityPythonServerlessSlo/Sli Frameworks

Artificial Intelligence
Own reliability for a US teleradiology platform running on GCP and Kubernetes. Define and manage SLOs and error budgets, improve observability through Grafana, lead incident response, write blameless postmortems, reduce operational toil, and integrate reliability into system design. Communicate availability and incidents clearly to engineers, clinicians, clinical operations, and commercial stakeholders. The role is remote within the United States and covers US business hours without overnight on-call duties.
Top Skills:
GCPGrafanaKubernetes
Cloud • Information Technology • Professional Services • Security
Designs, secures, and maintains Azure Government infrastructure supporting compliant, resilient cloud services. Responsibilities include zero-trust networking, automated patching and STIG enforcement, disaster recovery, Azure Virtual Desktop management, certificate rotation, monitoring, cost optimization, and audit evidence preparation. The role collaborates with security, compliance, DevSecOps, and SOC teams to meet FedRAMP, FISMA, and CMMC requirements.
Top Skills:
AnsibleAzure AutomationAzure FirewallAzure MonitorAzure NetworkingAzure PolicyAzure Site RecoveryAzure Virtual DesktopAzure Virtual NetworksBicepCmmcDod Il4Dod Il5FedrampFismaInfrastructure As CodeLog AnalyticsMicrosoft Azure GovernmentNetwork Security GroupsSsl/TlsStigTerraform
Cloud • Information Technology • Professional Services • Security
Designs, operates, and secures production GCP environments for federal and regulated customers handling CUI. Responsibilities include cloud foundations, networking, IAM, encryption, monitoring, threat detection, incident response, GKE security, infrastructure automation, observability, and compliance evidence. The role translates NIST, FedRAMP, and CMMC requirements into GCP controls and supports audit readiness while reducing operational toil through Terraform and scripting. It requires strong stakeholder communication and hands-on SRE, cloud security, and GCP expertise.
Top Skills:
Access Context ManagerArtifact RegistryBashBeyondcorp EnterpriseBigQueryBinary AuthorizationChronicleCloud ArmorCloud Audit LogsCloud BuildCloud DeployCloud DlpCloud EkmCloud Foundation ToolkitCloud HsmCloud KmsCloud LoggingCloud MonitoringCloud NgfwCmekGkeGoGoogle Cloud Platform (Gcp)Google Security OperationsIamIapInfrastructure ManagerKubernetesPythonSecurity Command CenterShared VpcSoarTerraformVpc Service ControlsWorkload Identity FederationYara-L
Fintech • Information Technology • Software • Consulting
Manage and maintain cloud infrastructure for performance, availability, and scalability. Deploy cloud environments, monitor system uptime and performance, support cloud migration and modernization initiatives, and implement infrastructure automation using AWS, Azure, or GCP, monitoring tools, and Infrastructure as Code.
Top Skills:
AWSAzureCloud Infrastructure MonitoringGoogle Cloud Platform (Gcp)Infrastructure As Code (Iac)Infrastructure Automation
AdTech
Build and maintain cloud-native infrastructure, automate manual operations, develop Terraform modules and Helm charts, manage Kubernetes and service mesh configurations, monitor GCP databases and services, improve observability, maintain CI/CD pipelines, and use AI coding agents to enhance infrastructure development. Collaborate with engineering teams on instrumentation, architecture, capacity planning, scalability, reliability, security, and developer experience.
Top Skills:
Amazon KinesisAWSAws LambdaAws SnsBigQueryClaude CodeCloudsqlCursorDatadogDockerGCPGitlabGoogle Cloud FunctionsGoogle Cloud RunGoogle Pub/SubGrafanaHelmIstioKafkaKubernetesMySQLPrometheusSpannerTerraform
Fintech • Software
The Senior Site Reliability Engineer maintains resilient, observable SaaS platforms through monitoring, alerting, automation, CI/CD, infrastructure as code, and performance optimization. The role leads incident response, triage, root-cause analysis, and 24/7 on-call operations while applying AI/AIOps for predictive reliability and automated remediation. Responsibilities include supporting cloud infrastructure, Kubernetes environments, production security, database performance, SLOs, SLAs, and continuous improvements in collaboration with software engineering teams.
Top Skills:
.NetAiopsAksAnsibleAppdynamicsAWSAzureAzure DevopsBashC#Ci/CdCloud NetworkingCloudopsCosmos DbDatadogDockerDynatraceEksFirewallsHarnessInfrastructure As CodeJavaJenkinsKubernetesLoad BalancingNew RelicPowershellPythonSQLTerraform

Cloud • Analytics
Design, operate, and support reliable customer platforms across Linux, Kubernetes, and public cloud environments. Responsibilities include OS lifecycle management, infrastructure automation, IaC, configuration management, GitOps, observability, SLOs, capacity planning, incident response, and on-call support. The role requires depth in one data platform area—Elasticsearch/OpenSearch, Redis, or Kafka-Hadoop-Spark—and willingness to learn others. It also involves customer consultation, platform architecture guidance, documentation, knowledge sharing, and reducing operational toil through scripting and automation.
Top Skills:
AnsibleArgo CdAWSAzureBashCdpChefClouderaCloudFormationConfluentDataprocEfkElasticsearchEmrEvent HubsFluxGCPGitopsGrafanaHadoopHelmKafkaKickstartKubernetesLinuxMskOpensearchPrometheusPuppetPythonRedisSaltSparkTerraform
Cloud • Security • Software • Cybersecurity
Analyzes large-scale telemetry and datasets to identify content delivery performance and reliability issues. Builds software tools to automate analytical workflows and enable autonomous diagnosis. Applies statistical analysis, machine learning, networking, and distributed-systems expertise to develop targeted platform improvements. Defines and mines internal data feeds, establishes performance indicators, and partners with Engineering, Operations, and Product teams to guide feature and process adoption.
Top Skills:
CC++Distributed SystemsDnsHTTPMachine LearningPythonTcpTls

One Month AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
Build and operate security infrastructure for MongoDB Atlas across AWS, Azure, and Google Cloud. Responsibilities include hardening Linux hosts and containers, implementing cloud security controls, workload identity, vulnerability management, Infrastructure-as-Code, runtime threat detection, and monitoring systems. The role leads initiatives from threat modeling and architecture through deployment and long-term production reliability.
Top Skills:
AnsibleApparmorAWSAzureCC++CgroupsCiliumCloudFormationEbpfFalcoGatekeeperGoGoogle Cloud PlatformKubernetesLinuxMongodb AtlasPythonRbacRustSeccompSelinuxTerraformTetragon
Financial Services
Configure and optimize Dynatrace SaaS Gen3 and SolarWinds monitoring across applications, infrastructure, cloud environments, Azure subscriptions, and networking. Build dashboards, reports, queries, alerts, and actionable insights for technical and business stakeholders. Collaborate with architecture, DevOps, security, SRE, and business teams to troubleshoot monitoring issues, maintain regulatory compliance, and document configurations, runbooks, and best practices.
Top Skills:
AzureDqlDynatrace Saas Gen3OneagentSolarwinds

Real Estate • Financial Services • PropTech
Leads site reliability engineering for AWS cloud environments, building infrastructure and Infrastructure as Code capabilities. Develops automation, CI/CD pipelines, monitoring, alerting, dashboards, and Kubernetes platforms; manages IAM, patching, vulnerabilities, repositories, and incident response. Identifies performance and availability issues, conducts post-incident analysis, collaborates with delivery and platform teams, and mentors engineers.
Top Skills:
.NetAmazon CloudwatchAmazon EksAWSAzure DevopsCloudFormationDatadogElastic BeanstalkGitGitIamInfrastructure As CodeJavaKubernetesMicrosoft Sql ServerPythonRdsTerraform

Cloud • Information Technology • Business Intelligence • Consulting
Design, build, and operate cloud infrastructure, deployment, observability, and reliability systems. Responsibilities include infrastructure-as-code, Kubernetes, CI/CD, incident response, SLOs, cost optimization, automation, production readiness, and support for hybrid, edge, on-premises, and customer-controlled environments. The role improves platform reliability, reduces operational toil, and enables safe, consistent delivery for mission-critical customers.
Top Skills:
AlertingAzureAzure ArcAzure DevopsBicepCi/CdDashboardsGithub ActionsGpu WorkloadsInfrastructure-As-CodeKubernetesLogsMetricsObservabilityTerraformTraces

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Los Angeles, CA Companies Hiring Remote Site Reliability Engineers
See All





Popular Job Searches
All Filters
Total selected ()
No Results
No Results
